AI Integration
AI integration services that wire LLMs, embeddings, and AI features into your product. Prompt-engineered pipelines built for reliable, production-grade behavior.
The gap is not access to the technology. Any team can call an API. The gap is reliability: shipping AI features that behave the same way on the ten thousandth request as they did in the demo.
AI integration as engineering, not experimentation
Calling a model is easy. Getting structured, accurate, grounded output from it inside a real product is systems engineering. The model is one component. The pipeline around it decides whether the feature works.
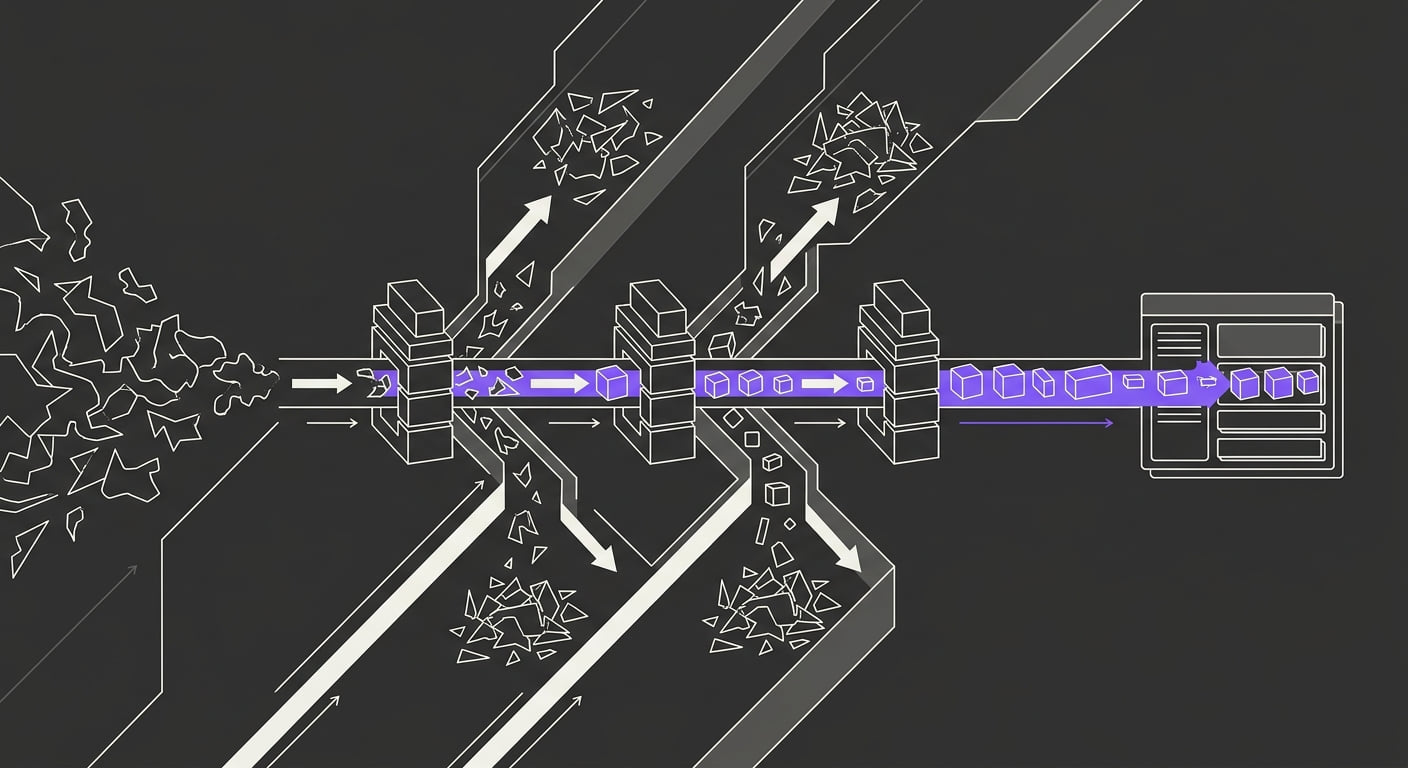
That pipeline is what gets built here: retrieval that pulls the right context, prompts engineered and versioned like code, validation on every response, and graceful degradation when the model is uncertain.
What you get
LLM feature development. Chat, summarization, classification, generation, and extraction wired into your product with typed contracts.
RAG pipelines. Embeddings and vector search over your own data, so answers come from your content instead of the model’s imagination.
Prompt engineering as infrastructure. Versioned, tested, evaluated prompts. Not strings pasted into source files.
Output validation. Schema checks, confidence thresholds, and human-review hooks where the stakes are high.
Cost controls. Response caching, model tiering, and context trimming so usage costs stay predictable as you scale.
Observability. Logging and tracing of every model interaction, because you cannot improve what you cannot see.
How the engagement runs
Use-case audit.
Pipeline design.
Build and evaluate.
Harden and monitor.
Where AI integration pays for itself
| Use case | Without structure | With engineered pipeline |
|---|---|---|
| Support answers | Hallucinated policies | Grounded in your docs |
| Document processing | Manual review of every output | Schema-validated extraction |
| Content generation | Generic filler | On-brand, constrained output |
| Search | Keyword matching | Semantic retrieval |
| Cost at scale | Unpredictable spikes | Cached, tiered, budgeted |
The demo takes an afternoon. The product takes discipline. Ship the second one.
Who this is for
SaaS teams adding AI features customers actually asked for. Businesses drowning in manual document or support work. Founders who want AI as a moat, not a gimmick. Teams that tried the API once, got unreliable results, and concluded AI was not ready. It was ready. The pipeline was missing.
Start integrating
OPENING DECEMBER 2026
Bring the workflow you want to automate or the feature your users keep requesting. The first conversation ends with an honest assessment of whether AI belongs there, what it will cost, and how long it will take.
Questions,
answered.
[ FAQ ]
Direct answers for founders and teams evaluating Huzaifa Web Studio as their technical partner.
Connecting large language models to your product so they do useful work: answering questions over your data, generating content, classifying input, or automating decisions. It covers API wiring, prompt engineering, retrieval pipelines, evaluation, and fallbacks when the model is wrong.
Yes. Model APIs are HTTP services, so they integrate with virtually any backend. The real work is architectural: where calls happen, how context is retrieved, and how output is validated before it reaches your users.
Structured prompts, retrieval grounded in your own data, schema-validated responses, and automated evaluation sets. Every feature ships with tests that measure answer quality, not just whether the API returned 200.
Token usage scales with traffic and context size. A typical product feature runs from tens to hundreds of dollars per month. Caching, smaller models for simple tasks, and context trimming keep the bill predictable.
Yes. The engagement starts with an audit of your current architecture, then identifies the highest-value integration points and the safest way to reach them without destabilizing the product.